Get to know Cadenya
We’re developers who love to build. We set out to create a yes-code platform that makes building agents feel like the best parts of building software.
The Architecture Behind Our SSE Streams
Nerding Out
$ whoami
> Robert Ross
$ date
> Thu Sep 17 8:15:47 EDT 2026
$ pwd
> Blue Bottle, 40 Bow St, Cambridge, MA 02138
Everywhere I look, there’s a chat box in a product now. If AIM were around today, it would be so pleased to see its impact on the modern web: Humans love to chat. Text box. Submit button. That’s it.
The problem with Server-Side Events (SSE) is not that streaming a message to an HTTP client is easy. That part is made simple now with plenty of open-source packages for every language.
The hard part is getting a message to that stream in the first place.
This Deep Dive
I found that most technical blogs that talk about SSE take a myopic point of view. They skip how data gets into the system and how it travels outside of it. They’ll say “Use Redis” and not much else.
This post is not that. It’s technical end-to-end. It’s handwritten. And it’s in production.
flowchart TB
  accTitle: SSE connections and the objective event architecture
  accDescr: SSE connections pass through Cloudflare, Envoy, and the HTTP SSE server to the gRPC event stream. Envoy also routes API requests to the gRPC API. Repositories persist objectives and events in Postgres. Pub/Sub subscribers start Temporal workflows and append objective events to Redis. The gRPC event stream reads live events from Redis and replay events from Postgres. Events return over the SSE connection.

  Cloudflare["Cloudflare"] --> Envoy["api.cadenya.com"]
  Envoy -->|SSE connection| HTTP["HTTP SSE server"]
  HTTP -->|gRPC stream| Stream["gRPC event stream"]
  Envoy -->|API request: JSON to gRPC| API["gRPC API<br/>Objective repository"]
  API -->|Persist objective| Postgres[("Postgres<br/>Durable history")]
  API --> Created["Pub/Sub: ObjectiveCreated<br/>Objective subscriber"]
  Created --> Temporal["Temporal<br/>Agent loop"]
  Temporal --> Events["Objective event repository"]
  Events -->|Persist event| Postgres
  Events --> Published["Pub/Sub: ObjectiveEventCreated<br/>SSE subscriber"]
  Published --> Redis[("Redis streams<br/>Live event fan-out")]
  Redis -->|Live events| Stream
  Postgres -.->|Replay after Last-Event-ID| Stream
The diagram could not be loaded. Its source is shown above.
Technology Choices
- Go - All of Cadenya’s backend is written in Go.
- Protobufs - Events are serialized into a protocol buffer at every point of their journey.
- Temporal - Temporal is not exactly in the critical path, but it’s important enough to mention.
- Pub/Sub - Google’s Pub/Sub product is a critical piece of Cadenya’s architecture.
- Redis - Redis streams are used heavily.
- gRPC Streams - Oh yeah, we’re getting this deep.
- Envoy - How we split traffic from our transcoded gRPC server to an SSE HTTP server.
Check that the SSE matches: This is not about streaming text chunks like you see in LLM APIs; however, the technology ideas are the same.
CQRS and Repositories Everywhere
The liberal usage of the CQRS design pattern in Cadenya means that storing data has a consistent interface design. And there’s a simple rule:
- Store the event in the database.
- Publish the event to the Pub/Sub topic (e.g.,
topics.v1.ObjectiveEventCreated).
The repositories are stored in a package structure like this:
internal/repositories/tools/repository.go
internal/repositories/objectives/repository.go
internal/repositories/agentschedules/repository.go
And each package always exports a Repository interface:
// Repository defines the interface for objective operations.
type Repository interface {
	CreateObjective(ctx context.Context, req *apiv1.CreateObjectiveRequest, opts ...CreateObjectiveOption) (*apiv1.Objective, error)
	GetObjective(ctx context.Context, req *apiv1.GetObjectiveRequest) (*apiv1.Objective, error)
	GetObjectiveDiagnostics(ctx context.Context, req *apiv1.GetObjectiveDiagnosticsRequest) (*apiv1.GetObjectiveDiagnosticsResponse, error)
	ListObjectives(ctx context.Context, req *apiv1.ListObjectivesRequest) (*apiv1.ListObjectivesResponse, error)
	ContinueObjective(ctx context.Context, req *apiv1.ContinueObjectiveRequest) (*apiv1.ObjectiveEvent, error)
	CreateContextWindow(ctx context.Context, objectiveID string) (*apiv1.ObjectiveContextWindow, error)
}
The repository type always uses protobufs as the arguments and return types for its methods. The interfaces for these domains usually match the gRPC RPC methods, too, making the server implementation mostly delegate to the repository. For example, this is an RPC method for agent schedules:
func (os *ObjectiveService) objectiveRepo(ctx context.Context) objectives.Repository {
	return objectives.NewRepository(os.GetDB(), &os.PubSub, os.masterKey, os.eventStore(ctx))
}

func (os *ObjectiveService) CreateObjective(ctx context.Context, req *apiv1.CreateObjectiveRequest) (*apiv1.Objective, error) {
	return os.objectiveRepo(ctx).CreateObjective(ctx, req)
}
This thin design means there’s always the same interface everywhere data is persisted to, or read from, the database.
The Agent Loop (i.e., Objectives)
When an Objective is created in Cadenya, it passes through the objectives.Repository interface, into our Postgres database, and into Google Pub/Sub. Once a record is stored in Postgres, the record is materialized into a corresponding Protobuf message. (That’s what the apiv1 package is all over this post.)
There’s a bit of “trickery” in our event publishing that uses (abuses?) Go’s generics to create a function that publishes our message. There are internal topicsv1 protobuf messages that act as envelopes to represent events in Pub/Sub. For example:
syntax = "proto3";

package topics.v1;

import "cadenya/api/v1/objective_context.proto";
import "cadenya/api/v1/objectives.proto";

option go_package = "go.cadenya.dev/internal/proto/topics/v1;topicsv1";

message ObjectiveCreated {
  cadenya.api.v1.Objective objective = 1;
  cadenya.api.v1.ObjectiveContextWindow context_window = 2;
}
When this message is generated using buf, it can be passed into our Publisher function from our pubsub package to generate the topic’s name using protoreflect. For example:
// PublishFunc publishes only T using the context bound by NewPublisher.
// Bind publishers within a request or activity so cancellation and tracing follow it.
type PublishFunc[T proto.Message] func(T, ...PublishOption) error

// NewPublisher binds a protobuf type to its topic and a publishing context.
// Go version 1.27 allows using generics on methods, so we can use T directly.
func (ps *PubSub) NewPublisher[T proto.Message](ctx context.Context) (PublishFunc[T], error) {
	return NewPublisher[T](ctx, ps)
}

// NewPublisher binds an interface-backed publisher to a protobuf type and context.
// Concrete PubSub dependencies also expose this as a generic method.
func NewPublisher[T proto.Message](ctx context.Context, backend Publisher) (PublishFunc[T], error) {
	var zero T
	message := zero.ProtoReflect().New().Interface()
	publish, err := backend.Publisher(message)
	if err != nil {
		return nil, err
	}
	return func(msg T, opts ...PublishOption) error {
		if !msg.ProtoReflect().IsValid() {
			return fmt.Errorf("pubsub: cannot publish nil %s", TopicName(message))
		}
		return publish(ctx, applyPublishOptions(opts).key, msg, opts...)
	}, nil
}
The backend.Publisher is an injectable interface that can be swapped for a Noop implementation for testing, too. If I’m feeling daring one day, this could be replaced with Kafka. But the publisher func is what returns a function that sends our message to a topic based on the proto message itself:
// Publisher returns a RawPublishFunc for the given message type.
func (ps *PubSub) Publisher(msg proto.Message) (RawPublishFunc, error) {
	// Converts the message to `topicsv1.ObjectiveCreated` for example
	topicName := string(msg.ProtoReflect().Descriptor().FullName())

	fn := func(ctx context.Context, key []byte, msg proto.Message, opts ...PublishOption) error {
		client, err := ps.getClient(ctx)
		if err != nil {
			return err
		}

		bytes, err := proto.Marshal(msg)
		if err != nil {
			return fmt.Errorf("could not marshal message for topic '%s': %w", topicName, err)
		}

		if len(key) == 0 {
			// Pub/Sub ordering keys are protobuf strings and must be valid UTF-8.
			key = []byte(rand.Text())
		}

		settings := applyPublishOptions(opts)
		attributes := publishAttributes(key, opts)

		pubsubMsg := &pubsub.Message{
			Data:       bytes,
			Attributes: attributes,
		}
		publisher := client.Publisher(topicName)
		defer publisher.Stop()
		if !settings.unordered {
			publisher.EnableMessageOrdering = true
			pubsubMsg.OrderingKey = string(key)
		}
		result := publisher.Publish(ctx, pubsubMsg)

		telemetry.Logger(ctx).Info("publishing message", "topic", topicName, "key_length", len(key), "value_length", len(bytes), "ordered", !settings.unordered)

		if _, err := result.Get(ctx); err != nil {
			return fmt.Errorf("could not publish message to topic '%s': %w", topicName, err)
		}

		return nil
	}

	return fn, nil
}- The interface method grabs the full name from the proto descriptor for the message. This resolves to the package name + the message name, e.g.,
topics.v1.ObjectiveCreated. - It constructs an anonymous function that will publish that message to the topic.
- The caller then uses that anonymous function to publish the message.
msg := (&topicsv1.ObjectiveEventCreated_builder{
	Objective: objective,
	Event:     eventPb,
}).Build()

publisher, err := pubsub.NewPublisher[*topicsv1.ObjectiveEventCreated](ctx, p)
if err != nil {
	return fmt.Errorf("could not create pubsub publisher: %w", err)
}

// Keyed by event ID, so every message is its own ordering group and an
// ordered publish only adds sequencing latency to the event path.
if err := publisher(msg, pubsub.WithOrderingKey([]byte(record.GetID())), pubsub.WithoutOrdering()); err != nil {
	return fmt.Errorf("could not publish objective event: %w", err)
}
The flow at this point looks like this:
POST api.cadenya.com
  -> Cloudflare
    -> Envoy JSON-gRPC Transcoder
      -> gRPC Server RPC
        -> Pass message to Repository as-is
          -> Store in Database
            -> Publish to Pub/Sub Topic
All of our topics and subscriptions for Pub/Sub are stored in a config/pubsub.yaml file in the repository that is embedded into the cadenya binary that is compiled. It contains this structure:
topics:
  - name: topics.v1.ObjectiveCreated
    subscriptions:
      - name: topics-v1-ObjectiveCreated--objectives
        filter: NOT attributes:parent_objective_id
      - name: topics-v1-ObjectiveCreated--pusher
      - name: topics-v1-ObjectiveCreated--analytics

  - name: topics.v1.ObjectiveContinued
    subscriptions:
      - name: topics-v1-ObjectiveContinued--objectives
      - name: topics-v1-ObjectiveContinued--pusher
Cadenya uses filters at the Pub/Sub subscription layer to prevent subscribers from getting messages they don’t need to process in some scenarios. For example, for sub-agents, we don’t want our --objectives subscriber to process them, because the logic in that subscriber is not necessary for sub-objectives. Don’t sleep on this feature of Pub/Sub - it’s powerful.
One Mild Rule
In general, Temporal workflows are triggered from Pub/Sub subscribers. I.e., the CQRS layer rarely starts a workflow directly. There are a few reasons for this:
- Fanning out “subscribers” from a Temporal workflow is an anti-pattern.
- It’s also expensive (in money, moolah, not CPU) to treat Temporal like a message subscriber.
- Subscriptions are more open-closed than Temporal when we need to add downstream side effects for published messages.
Instead, repositories (almost) always push messages to Pub/Sub, and if a Temporal workflow needs to be started, it is started from a Pub/Sub subscriber.
Yes, The Outbox Pattern is also something you’d expect to see here. That’s an architecture Cadenya will adopt when it needs to.
The Journey of an Event
Once the Pub/Sub message is produced, a consumer for newly created objectives takes the message and starts a Temporal workflow for the objective.
Cadenya also uses protobufs for Temporal workflow and activity parameters, and those messages may reference the public API messages, too. This is a beautiful thing, because it means our serialized messages match the same signatures as our repository layer, too. If you take one thing away from this blog, make it “Use protobufs in Temporal workflow and activity parameters.”
Anyway. Here’s the subscriber code that receives our topicsv1.ObjectiveCreated message and starts the workflow. It is registered as a subscription on our Pub/Sub client for the topicsv1.ObjectiveCreated topic.
func (c *Consumers) HandleObjectiveCreated(ctx context.Context, msg *topicsv1.ObjectiveCreated) error {
	objective := msg.GetObjective()
	contextWindow := msg.GetContextWindow()

	loadJIT, err := c.jitResolver.HasJustInTimeToolSets(ctx, objective)
	if err != nil {
		return fmt.Errorf("could not resolve just-in-time tool sets: %w", err)
	}

	input := (&objectiveworkflowsv1.AgentObjectiveWorkflowInput_builder{
		Objective:           objective,
		ContextWindow:       contextWindow,
		LoadJustInTimeTools: loadJIT,
	}).Build()

	// Start our workflow with the constructed protobuf message
	if _, err := c.GetTemporalClient().ExecuteWorkflow(ctx, client.StartWorkflowOptions{
		TaskQueue:                                objectiveworker.TaskQueue,
		ID:                                       objective.GetMetadata().GetId(),
		WorkflowIDReusePolicy:                    enumspb.WORKFLOW_ID_REUSE_POLICY_REJECT_DUPLICATE,
		WorkflowExecutionErrorWhenAlreadyStarted: true,
	}, objectiveworker.AgentObjectiveWorkflow, input); err != nil {
		if temporal.IsWorkflowExecutionAlreadyStartedError(err) {
			telemetry.Logger(ctx).Info("objective workflow already started; acking", "objective_id", objective.GetMetadata().GetId())
			return nil
		}
		return fmt.Errorf("could not enqueue AgentObjectiveWorkflow: %w", err)
	}

	return nil
}
The Workflow
When an agent starts a new objective in Cadenya, its progress is recorded as objective events: things like assistant responses, tool calls and results, approval requests and decisions, compaction, and lifecycle changes.
At a high level, the Temporal orchestration has three main workflow layers:
AgentObjectiveWorkflow→ Uses the objective’s configuration snapshot, loads callable tools, and drives the iteration loop.IterationWorkflow→ Calls the LLM with the objective’s conversation history, records the response, and returns either tool requests or completion.CallToolWorkflow→ Handles one requested tool call, including approval, execution, and recording its result. The objective workflow starts these children in parallel, then waits for their results before the next iteration.
For example, when the CallToolWorkflow fires, it will use the objectiveevents.Repository to store the new events.
The ObjectiveEvent repository is similar to the RPC-facing methods, too. Nothing creates this record from the API surface.
// From: internal/repositories/objectiveevents/repository.go
type Repository interface {
	CreateEvent(ctx context.Context, objective *apiv1.Objective, event *apiv1.ObjectiveEvent, opts ...CreateEventOption) (*ent.ObjectiveEvent, error)
}
The implementation of this method is where a few things happen:
- Create the Objective Event record in the database.
- Publish the event to the Pub/Sub topic
topics.v1.ObjectiveEventCreated(just like our objectives). - Pub/Sub subscriber(s) grab the event.
flowchart TB
  accTitle: Objective events from the repository to Redis
  accDescr: After storing an objective event in Postgres, the repository publishes ObjectiveEventCreated to Google Pub/Sub. The SSE subscriber receives the message and appends the event to the objective's Redis stream.

  repository["objectiveevents.Repository<br/>Store event in Postgres"]
  topic["Google Pub/Sub topic<br/>topics.v1.ObjectiveEventCreated"]
  subscriber["SSE subscriber<br/>WriteObjectiveEventToStream"]
  redis[("Redis stream<br/>objective_events:objectiveID")]

  repository -->|Publish| topic
  topic -->|Deliver| subscriber
  subscriber -->|XADD| redis
The diagram could not be loaded. Its source is shown above.
The ObjectiveEvent message is an envelope with a data field that stores a variety of event messages: assistant messages, tool calls, etc. The protobuf looks like this:
message ObjectiveEvent {
  OperationMetadata metadata = 1;

  // See the message below
  ObjectiveEventData data = 2;
  string context_window_id = 3;
  ObjectiveEventInfo info = 4 [(gnostic.openapi.v3.property) = {read_only: true}];
  google.protobuf.Duration duration = 5 [(gnostic.openapi.v3.property) = {read_only: true}];
  google.protobuf.Timestamp started_at = 6 [(gnostic.openapi.v3.property) = {read_only: true}];
}

message ObjectiveEventData {
  string type = 1 [(cadenya.api.v1.discriminator_for) = "data"];

  oneof data {
    UserMessage user_message = 9;
    AssistantMessage assistant_message = 10;
    ToolApprovalRequested tool_approval_requested = 11;
    ToolApproved tool_approved = 12;
    ToolDenied tool_denied = 13;
    ToolCalled tool_called = 14;
    // ... way more were here
    Reasoning reasoning = 28;
  }
}
The oneof data field is used to discriminate between the different event types and allows the message to have proper types. Messages in proto can have up to 65,535 fields, so abusing the protobuf Any type felt like a sin in this case. We should always know the type of event in the message. Go has a nice helper method that is added when using oneof in a message that can be used in a switch statement, too.
When a message serializes to JSON, it’s, well, quite large and revealing of internals.
{
  "metadata": {
    "id": "objevt_01M233CJHEQWVF63RC797NTN46",
    "accountId": "account_01M1N6K41JTKMJE43WH213AFDX",
    "workspaceId": "workspace_01M1N6K4T1BW6TJF6N6F2F3135",
    "labels": {},
    "createdAt": "2026-09-09T12:48:20.014375Z",
    "externalId": "",
    "profileId": ""
  },
  "data": {
    "type": "assistantMessage",
    "assistantMessage": {
      "toolCalls": [
        {
          "arguments": "{\n  \"cursor\": null,\n  \"includeInfo\": false,\n  \"labels\": null,\n  \"limit\": 10,\n  \"prefix\": null,\n  \"query\": null,\n  \"sortOrder\": null,\n  \"state\": null\n}",
          "functionName": "ToolService_ListToolSets"
        }
      ]
    }
  },
  "contextWindowId": "objwin_01M233CFFGKZ0S0222FSJ4PFT3",
  "info": {
    "createdBy": {
      "metadata": {
        "id": "profile_01M1N6K62KY6DTT865HRNJZPCV",
        "accountId": "account_01M1N6K41JTKMJE43WH213AFDX",
        "name": "Caddy",
        "externalId": "",
        "labels": {},
        "profileId": ""
      },
      "spec": {
        "email": "system@cadenya.internal",
        "name": "Caddy",
        "type": "PROFILE_TYPE_UNSPECIFIED"
      }
    }
  },
  "duration": "1.320s",
  "startedAt": "2026-09-09T12:48:18.621650Z"
}
This event, in its entirety, goes to Pub/Sub for the subscriber to grab.
Where SSE Starts
I’m sorry it took this long to get here. But, to be fair, I did warn you at the beginning that this post was deep. But we’re at the part of the post that is in the title: Server-Sent Events.
The consumer for every single objective event is responsible for pushing the objective event to Redis. The consumer is lightweight. Its only responsibility is to take the message from Pub/Sub and append it to the Redis stream key, while removing any attributes that are huge so we don’t accidentally blow up Redis (and therefore our downstream SSE clients).
func (c *Consumers) WriteObjectiveEventToStream(ctx context.Context, msg *topicsv1.ObjectiveEventCreated) error {
	objective := msg.GetObjective()
	event := msg.GetEvent()
	objectiveID := objective.GetMetadata().GetId()

	if err := c.sseStream.Append(ctx, objectiveID, sse.StripLargeEventContent(event)); err != nil {
		return fmt.Errorf("sse: could not append event: %w", err)
	}

	return nil
}
This calls into our internal/sse/sse.go package for Redis streams. The Append call is implemented like this:
// NewRedisStream builds a RedisStream over the given client.
func NewRedisStream(client *goredis.Client) *RedisStream {
	return &RedisStream{client: client}
}

func streamKey(objectiveID string) string {
	return "objective_events:" + objectiveID
}

// Append implements Stream.
func (s *RedisStream) Append(ctx context.Context, objectiveID string, event *apiv1.ObjectiveEvent) error {
	payload, err := proto.Marshal(event)
	if err != nil {
		return fmt.Errorf("sse: marshal event: %w", err)
	}

	key := streamKey(objectiveID)
	pipe := s.client.TxPipeline()
	pipe.XAdd(ctx, &goredis.XAddArgs{
		Stream: key,
		MaxLen: 200,
		Approx: true,
		Values: map[string]any{"event": payload},
	})
	pipe.Expire(ctx, key, 30*time.Minute)
	if _, err := pipe.Exec(ctx); err != nil {
		return fmt.Errorf("sse: append to stream %s: %w", key, err)
	}
	return nil
}
The above code uses the XADD command to append the objective event to the stable key identifier that looks like objective_events:obj_123ABC456. The stream’s max length is 200 (so we don’t end up storing an insane amount of data for no reason), and we store the raw bytes from the protobuf, too.
So our flow starts to take shape like this:
ObjectiveCreated
  -> Pub/Sub Consumer (`topicsv1.ObjectiveCreated`)
    -> Start Temporal Workflow
      -> Create Objective Event
        -> Pub/Sub Consumer (`topicsv1.ObjectiveEventCreated`)
          -> Push to Redis Stream
Once the message is in Redis, it’s more or less stationary in that key (up until ~200 items, that is). What makes the “stream” is when a client connects and asks Redis to “press play” and send messages starting at a certain offset to it.
gRPC Streaming
If you read the Designing Cadenya’s API post, you know that Cadenya heavily uses gRPC to define an OpenAPI spec (and SDKs) for the platform. The gRPC protocol itself is not capable of sending SSE events. There’s a separate, stupid simple HTTP server that acts as a proxy between Cadenya’s gRPC endpoint and the client.
The protocol buffer to define the stream endpoint for Cadenya looks like this:
syntax = "proto3";

package cadenya.api.v1;

import "cadenya/api/v1/objectives.proto";
import "cadenya/api/v1/options.proto";
import "gnostic/openapi/v3/annotations.proto";
import "google/api/annotations.proto";

option go_package = "go.cadenya.dev/api/cadenya/api/v1;apiv1";

message StreamObjectiveEventsRequest {
  string workspace_id = 1;
  string objective_id = 2;
}

service ObjectiveEventStreamsService {
  rpc StreamObjectiveEvents(StreamObjectiveEventsRequest) returns (stream ObjectiveEvent) {
    option (cadenya.api.v1.required_scope) = "objectives:read";
    option (google.api.http) = {get: "/v1/workspaces/{workspace_id}/objectives/{objective_id}/events:stream"};
    option (gnostic.openapi.v3.operation) = {
      summary: "Stream objective events"
      description: "Streams events for an objective in real-time using server-sent events (SSE)"
      tags: "Objectives"
    };
  }
}
By defining it in our gRPC services, it also becomes a part of our SDKs automatically.
The implementation of this endpoint is straightforward:
- Find the objective in the database (to make sure it actually exists for the profile).
- Attach to the Redis stream.
- For any new key on the Redis stream, forward the bytes verbatim to the gRPC stream.
The Last-Event-ID header is honored, too. Because all IDs in Cadenya are prefixed ULIDs, it’s a simpler operation to grab every objective event since a particular ID. A simple id > lastEventId is used on the objective_events table (ULID’s aren’t perfectly sorted, but this is acceptable here). Then they are sent to the gRPC stream.
The order of operations is:
Last Event ID
If Last-Event-ID is present, use the appropriate Repository to grab objective events where id > lastEventId (since IDs are ULIDs). Those records are sent to the gRPC stream before the live tail starts, and each event’s ID is stored in a map[string]struct{}{} set so that the event is not accidentally replayed by the live tail. It’s possible a new event arrived after the client received its last ID and before the live tail started, so you must implement this deduplication logic.
Tailing the Redis Stream
Because our stream key in Redis is stable based on the objective.metadata.id, we can read events off of the stream using XREAD. Cadenya sets the block parameter to 5 seconds, so the command will block for up to 5 seconds before we need to restart it.
Tailing a stream in Go looks like this in the Cadenya codebase:
func (s *RedisStream) Tail(ctx context.Context, objectiveID string, fromID string, out chan<- *apiv1.ObjectiveEvent) error {
	key := streamKey(objectiveID) // objective_events:obj_123ABC456
	lastID := fromID

	for {
		if ctx.Err() != nil {
			return nil
		}

		// Read events from the lastID, and wait for 5 seconds if there are none
		res, err := s.client.XRead(ctx, &goredis.XReadArgs{
			Streams: []string{key, lastID},
			Block:   s.block(),
		}).Result()
		if err != nil {
			if errors.Is(err, goredis.Nil) {
				// No new entries within this block window; recheck ctx and retry.
				continue
			}
			if ctx.Err() != nil {
				return nil
			}
			return fmt.Errorf("sse: tail stream %s: %w", key, err)
		}

		if len(res) == 0 {
			continue
		}
		// XREAD requests one stream, so only its messages need iterating.
		for _, msg := range res[0].Messages {
			event, err := decodeEvent(msg)
			if err != nil {
				return err
			}
			select {
			case out <- event:
			case <-ctx.Done():
				return nil
			}
			lastID = msg.ID
		}
	}
}
The out chan<- *apiv1.ObjectiveEvent argument is passed in from the gRPC service and is read to push the objective event as-is to the stream. The $ is used to tell Redis “only events since the command was issued.”
func (os *ObjectiveService) streamObjectiveEvents(req *apiv1.StreamObjectiveEventsRequest, stream grpc.ServerStreamingServer[apiv1.ObjectiveEvent]) error {
	events := make(chan *apiv1.ObjectiveEvent)
	done := make(chan error, 1)

	go func() {
		defer close(events)
		done <- os.sseStream.Tail(stream.Context(), req.GetObjectiveId(), "$", events)
	}()

	// The `Last-Event-ID` replay from our Postgres events is in this piece, because we need to make sure that the client's `Last-Event-ID` is respected before we start sending events.
	// but also dont want to _miss_ events since the connection was opened. Thats why the Redis tail is started first.

	// Iterate over the events being sent to our objective event channel
	// and send them to the gRPC stream
	for event := range events {
		if err := stream.Send(event); err != nil {
			return err
		}
	}

	return <-done
}
So our gRPC service endpoint starts a loop that grabs messages off of the Redis stream and forwards each proto message (which is an apiv1.ObjectiveEvent anyway) to the client. This architecture allows multiple stream connections to receive events for the same objective ID.
HTTP -> gRPC
The gRPC server is then used by an HTTP server that is drop-dead simple. It connects (via gRPC) to the service and streams the events over SSE using the go-sse package, imported as gosse (which I keep reading as Ryan Gosling, for some reason). The HTTP endpoint uses Chi, as well.
This is an example of the HTTP endpoint that streams events over SSE, with plenty redacted to make it clear what the core logic is.
// Register mounts the stream route on the router.
func (h *StreamHandler) Register(r chi.Router) {
	r.Get(
		"/v1/workspaces/{workspaceID}/objectives/{objectiveID}/events:stream",
		h.stream,
	)
}

func (h *StreamHandler) stream(w http.ResponseWriter, r *http.Request) {
	req := (&apiv1.StreamObjectiveEventsRequest_builder{
		WorkspaceId: chi.URLParam(r, "workspaceID"),
		ObjectiveId: chi.URLParam(r, "objectiveID"),
	}).Build()

	// Forward the reconnect cursor as outgoing gRPC metadata.
	ctx := r.Context()
	if lastEventID := r.Header.Get("Last-Event-ID"); lastEventID != "" {
		ctx = metadata.AppendToOutgoingContext(ctx, "last-event-id", lastEventID)
	}

	stream, err := h.client.StreamObjectiveEvents(ctx, req)
	if err != nil {
		http.Error(w, "could not open event stream", http.StatusBadGateway)
		return
	}

	w.Header().Set("Content-Type", "text/event-stream")
	w.Header().Set("Cache-Control", "no-cache")
	w.Header().Set("X-Accel-Buffering", "no")

	rc := http.NewResponseController(w)
	if err := rc.Flush(); err != nil {
		return
	}

	for {
		event, err := stream.Recv()
		if err != nil {
			return
		}

		payload, err := protojson.Marshal(event)
		if err != nil {
			return
		}

		msg := &gosse.Message{}

		// Only durable events advance the client's reconnect cursor.
		eventID := event.GetMetadata().GetId()
		if objectiveheartbeat.DurableID(eventID) {
			if id, err := gosse.NewID(eventID); err == nil {
				msg.ID = id
			}
		}
		if typ, err := gosse.NewType(event.GetData().GetType()); err == nil {
			msg.Type = typ
		}
		msg.AppendData(string(payload))

		if _, err := msg.WriteTo(w); err != nil {
			return
		}
		if err := rc.Flush(); err != nil {
			return
		}
	}
}
Note: This snippet also doesn’t include all of the insanity that sends ping events to keep the connection alive so load balancers don’t close it. You will need to send something to keep connections alive most of the time.
Now, when connecting to Cadenya’s streaming endpoint, you can see the events streaming through this architecture:
curl -H "Authorization: Bearer $CADENYA_API_KEY" https://api.cadenya.com/v1/workspaces/$CADENYA_WORKSPACE_ID/objectives/obj_01M24MDEF5V8KNNHT72VSNTHAQ/events:stream
event: open
data: {"time":"2026-09-10T03:05:48Z"}

id: objevt_01M24MF2CW7M68R7G6BAD1P3A9
event: toolApproved
data: {"metadata":{"id":"objevt_01M24MF2CW7M68R7G6BAD1P3A9","accountId":"account_01M1N6K41JTKMJE43WH213AFDX","workspaceId":"workspace_01M1N6K4T1BW6TJF6N6F2F3135","createdAt":"2026-09-10T03:06:02.012624427Z"},"data":{"type":"toolApproved","toolApproved":{"toolCallId":"toolcall_01M24MDKPS1CZZZY9TGN07PVD6"}},"contextWindowId":"objwin_01M24MDEGF5G7SA8W97P0RYQJV"}

id: objevt_01M24MF2H3YXJAVBS7KP38V4JC
event: toolCalled
data: {"metadata":{"id":"objevt_01M24MF2H3YXJAVBS7KP38V4JC","accountId":"account_01M1N6K41JTKMJE43WH213AFDX","workspaceId":"workspace_01M1N6K4T1BW6TJF6N6F2F3135","createdAt":"2026-09-10T03:06:02.147137076Z"},"data":{"type":"toolCalled","toolCalled":{"toolCallId":"toolcall_01M24MDKPS1CZZZY9TGN07PVD6","tool":{"type":"tool","tool":{"id":"tool_01M1N98JTJ182DCYVVM45Z71VT","accountId":"account_01M1N6K41JTKMJE43WH213AFDX","workspaceId":"workspace_01M1N6K4T1BW6TJF6N6F2F3135","name":"GenerateFake","profileId":"profile_01M1N6K62KY6DTT865HRNJZPCV","createdAt":"2026-09-04T04:01:38.642237Z"}},"config":{"type":"mcp","mcp":{}},"arguments":{"name":"name"}}},"contextWindowId":"objwin_01M24MDEGF5G7SA8W97P0RYQJV"}

event: ping
data: {"time":"2026-09-10T03:06:03Z"}
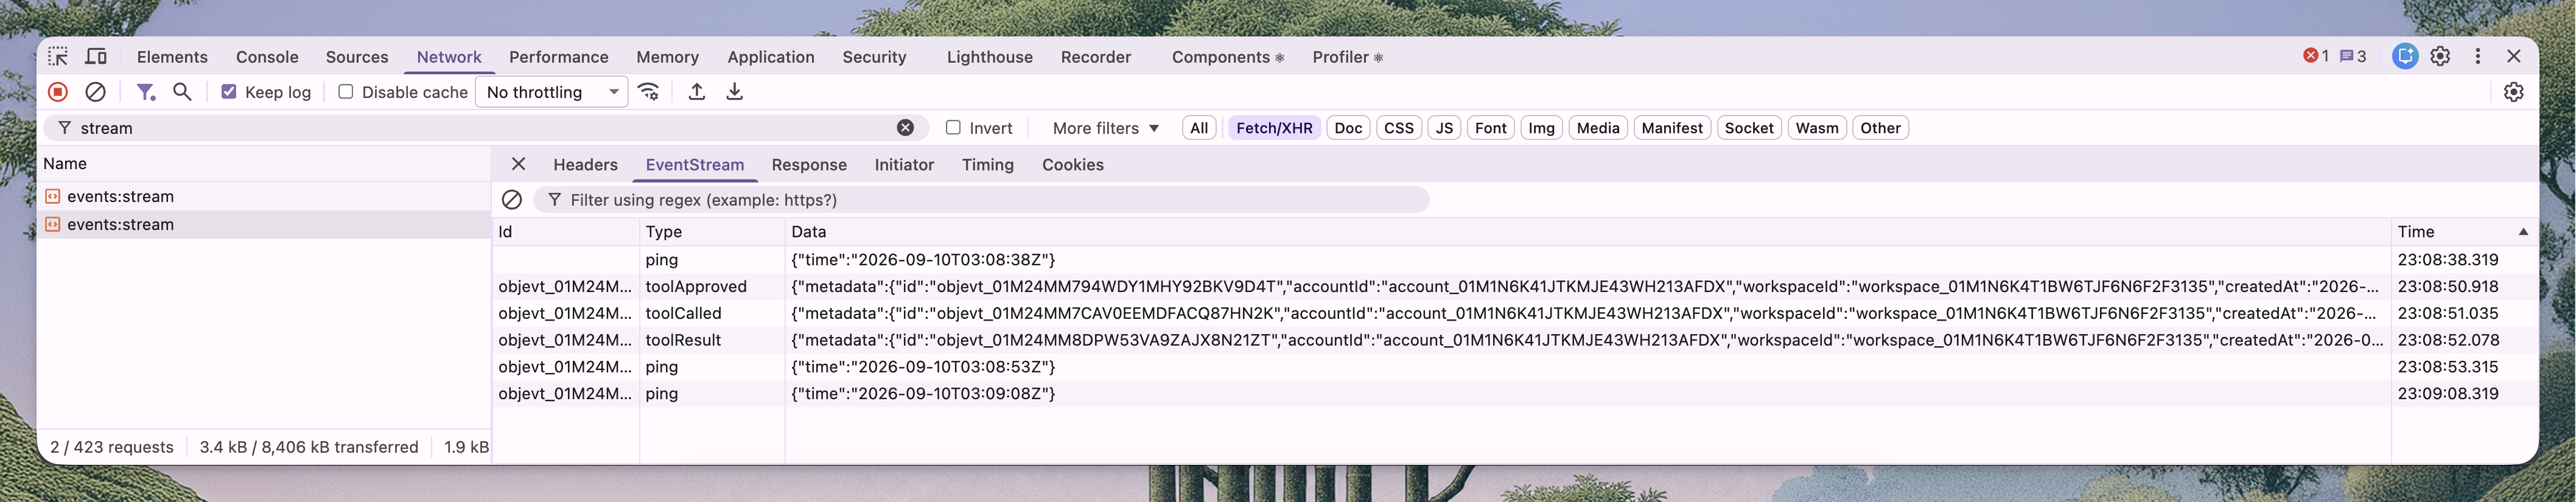
The developer console in Chrome (and I assume others) also supports displaying these events natively.
And here’s the final flow:
ObjectiveCreated
  -> Pub/Sub Consumer (`topicsv1.ObjectiveCreated`)
    -> Start Temporal Workflow
      -> Create Objective Event
        -> Pub/Sub Consumer (`topicsv1.ObjectiveEventCreated`)
          -> Push to Redis Stream
            -> gRPC ObjectiveEvent Stream
              -> HTTP Stream (SSE)
                -> HTTP Client
Wrapping Up
Most of the implementation of Server-Sent Events is not the component that streams events over an HTTP connection. That part, for all intents and purposes, is easy enough. What makes SSE difficult to implement in production is the architecture that surrounds how a message even gets into the Redis key, and therefore the stream, in the first place.
I hope you enjoyed it. Oh, and try out Cadenya for building your next agent. You’ll see this architecture in play with your own eyes.
Grow wherever AI goes next.
Start shipping agents that are equipped to evolve.